A recommendation has to be compatible and purchasable, not only popular.
Start with the shopper's task, not the engine. If shoppers cannot find the primary item, fix search and attributes first. For suggestions around a known item or basket, test native recommendations. Compare an established product when managed ranking and supported integrations fit the journey. Build custom only for a material gap in compatibility, account entitlements, or channels—and distinguish a custom integration from a custom model.
A parts seller showing incompatible accessories needs verified compatibility data before another engine. A fashion store with clean attributes and usable session data can test native related products first. These are decision examples, not predictors of sales lift. Require evidence of value before expanding, using a randomized holdout where traffic and measurement support it.
Choose the route that solves the actual task
Use search when a shopper expresses a query; use recommendations when the store proposes choices around an item, basket, or permitted context. A quiz or configurator may serve a complex need better than prediction. Replenishment may need reliable reorder controls, especially when items are discontinued or pack sizes change.
Repair search and attributes when people cannot find the primary item or verified replacement. Test exact-SKU, attribute, and replacement tasks. This is the wrong intervention when shoppers already find the main product and the demonstrated gap is a useful add-on.
Use native recommendations when supported related/complementary features meet the placement and rules. Verify actual theme/edition support, eligible results, withdrawal, and fallback. Native is a weak fit when an important account, compatibility, or channel rule cannot be enforced.
Choose specialist recommendation SaaS when managed ranking and supported integrations match the journey. Demand mapped catalog/events, serving restrictions, timeout fallback, deletion/export arrangements, and operating cost. An engine does not resolve broken identifiers or missing source ownership.
Consider a cloud ML service when your team can own application integration around a suitable managed model service. Check datasets, request filters, freshness, monitoring, and fallback. Do not expect the service to supply the storefront, live business rules, and operations automatically.
Build a custom model only when a tested requirement cannot be met acceptably by supported alternatives. Require versioned evaluation, owned serving interfaces, cold-start/failure tests, and lifecycle cost. Unreliable inputs are not an argument for a more complex model.
Curated or segment rules use approved relationships or groups; content-based methods use attributes; collaborative methods use interaction patterns; hybrids combine signals. A conversational interface adds clarification, not new product truth. “Often bought together” is association, not proof of compatibility. An existing engine behind tested account/fit controls may solve the gap without a new model.
What platform features do—and do not—give you
Shopify Search & Discovery supports related and complementary products. Verify the current theme, product-display and inventory conditions for related and complementary products in the actual store.
Adobe Commerce Product Recommendations uses behavioral and catalog data for recommendation units. It is a Commerce service, not a feature to assume in every Magento installation. Verify the product, frontend integration, and data restrictions; Adobe explicitly identifies it as not HIPAA-ready.
Amazon Personalize filtering supports custom criteria on recommendation requests. That capability is not a promise of instant stock synchronization or application fallback. A supported connector still needs a demonstrated path from source record and event to displayed card.
Define the integration contract before model selection
Agree three contracts around either an existing or a new engine:
No doubled purchase, invented click, unauthorized identity join, or cross-account exposure
Use consistent definitions on web and mobile. If a shopper is not legitimately identified across devices, do not treat two sessions as one person; contextual or session-based suggestions may suffice. Resolve overlapping local SKUs in multi-brand catalogs and decide whether recommendations may cross brands. Shared data does not authorize shared visibility.
Agree collection purpose, retention, access, and deletion with privacy/security owners. A technical connection is not a legal basis for personal-data use. Sparse histories, incomplete attributes, and mismatched events can make every engine a weak choice. Repair the inputs; an eligible curated/category fallback can be useful, but generic popularity is not individualized knowledge.
Work through a multi-brand parts-cart example
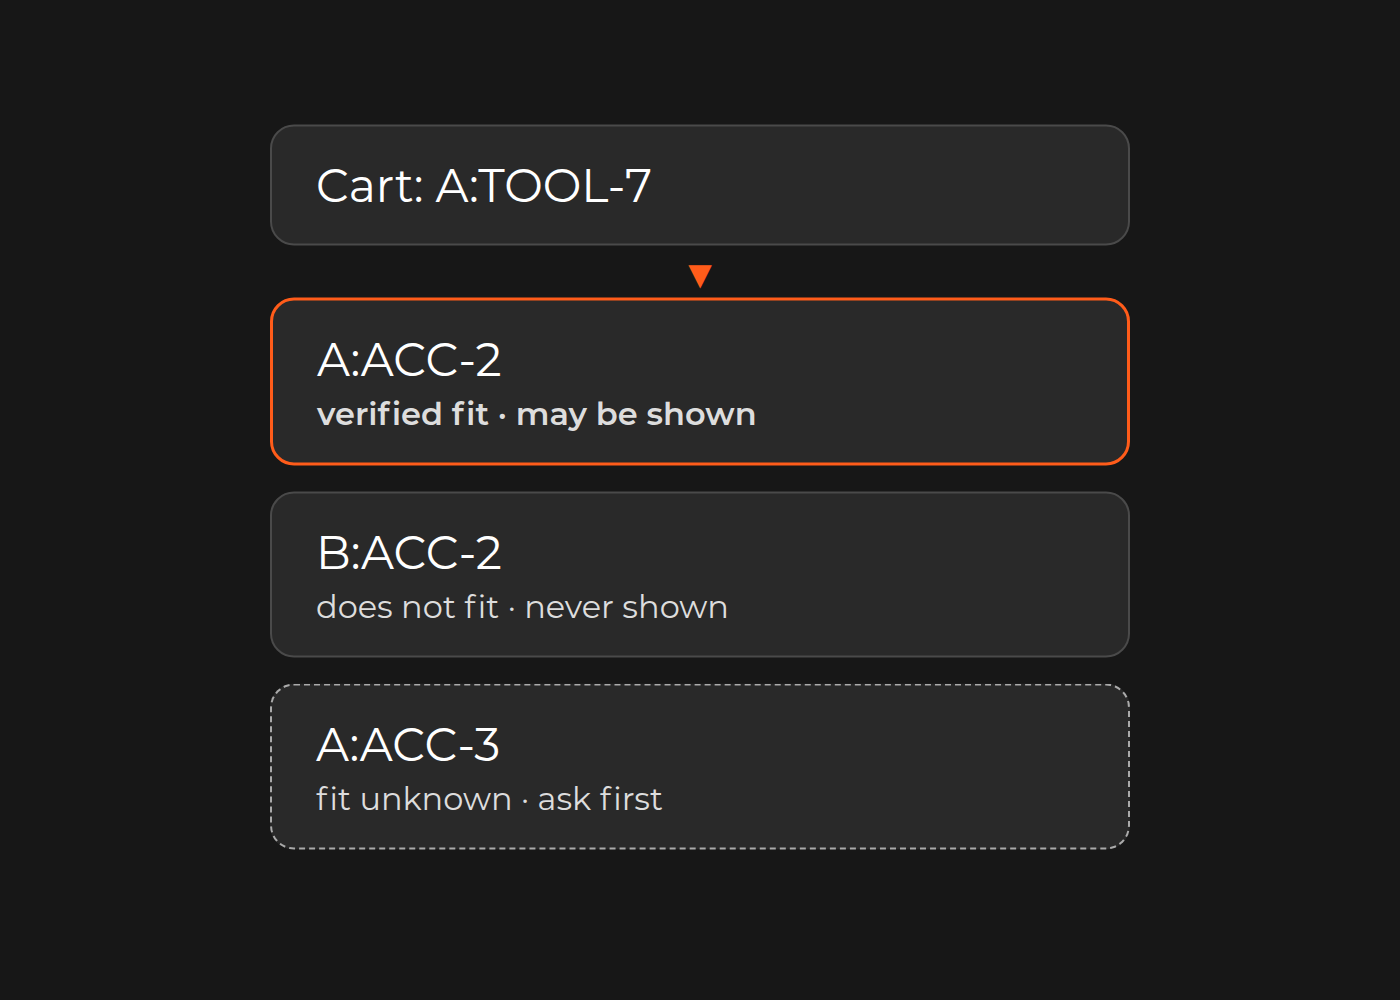
This fictional seller uses brand-plus-SKU identity because Brands A and B have overlapping local numbers. A:TOOL-7 is in the cart. The catalog owner verifies that A:ACC-2 fits; B:ACC-2 does not. A:ACC-3 has unknown fit. The engine may rank candidates, but serving checks fit, account rights, and availability before returning cards.
Use this recommendation acceptance set to start a comparison. Its rows are fictional, not a benchmark or client record:
Buyer task
Constraint
Expected result
Add an accessory to A:TOOL-7
Verified fit; account permits A:ACC-2; sellable
A:ACC-2 may be shown; B:ACC-2 must not
Ask whether A:ACC-3 fits
Compatibility evidence missing
Clarify or hand off; do not call it compatible
Repeat on a restricted account
A:ACC-2 not permitted
Exclude it, including from cache/fallback
Withdraw A:ACC-2 during session
Item no longer sellable
Remove/recheck; do not copy it silently into cart
Retain the source of each fit decision and the catalog/rule version. If a suggestion proceeds to cart or quote, recheck price and availability and show changes before confirmation. A timeout should leave checkout usable: hide the placement or serve a verified eligible fallback. A duplicate mobile purchase event must not become a second purchase in evaluation. These are proposed tests, not delivered-client behavior.
Prove correctness first, then incremental value
Use a reviewer-approved set covering cold starts, restricted items, incompatible combinations, no suitable answer, stale feeds, and account changes. Compare against the same baseline. Keep relevance separate from forbidden results, response time, and task completion; a good average must not hide an unsafe suggestion. Test withdrawal, dependency failure, timeout, and rollback.
The catalog/category owner accepts facts and compatibility. IT or the data lead owns identifiers, event/serving contracts, privacy coordination, and failure tests. The ecommerce lead defines the buyer outcome; the authorized sponsor approves the investment. Technical acceptance establishes behavior, not sales lift.
Where feasible, compare current and proposed experiences with randomized assignment. Define eligible traffic, assignment unit, primary outcome, guardrails, minimum useful effect, observation window, and analysis before launch. Choose session-, customer-, or account-level assignment for the journey to reduce contamination, while respecting cross-device identity limits.
Analyze all assigned eligible participants, not just recommendation clickers. Clickers are a selected group; their purchases alone do not establish added value. Track the commercial outcome alongside latency, errors, returns where observable, and support burden. Inspect stock, promotion, and channel differences.
A flat or inconclusive result is valid. If traffic or measurement cannot support a reliable comparison, say so. Usability and technical correctness can still be assessed; do not rename them a revenue experiment.
What Dinarys' relevant public work establishes
Dinarys' BigCommerce case for an unnamed office-supplies wholesaler describes AI-assisted categorization, product-data updates, theme/menu work, custom checkout, and request-to-quote. That is a real catalog/commerce component relevant to preparing recommendation inputs. It is not proof of a delivered recommendation engine, AI shopping consultant, or measured recommendation uplift.
For missing attributes or taxonomy, PIM services may be the appropriate first scope. For a remaining connected customer-experience gap, review Dinarys' ecommerce personalization services against your own input and acceptance contract. A service offer is not a substitute for implementation evidence or a promise that a custom model is needed.
Cost—and when to stop
Effort follows catalog readiness, placement count, event instrumentation, identity boundaries, service/API usage, web/mobile coverage, custom rules, experimentation, and operations. Include recurring service fees, review, and maintenance—not just implementation. There is no universal price for “AI recommendations.”
Keep native features when they meet the need. Stop adding complexity when evidence does not justify operating cost, distinguishing an inconclusive experiment from evidence of no useful effect. For the broader placement and promotion question, see ecommerce merchandising.
To compare options for one recommendation placement with Dinarys, bring a sanitized category sample, compatibility sources, representative buyer questions, correct/forbidden SKUs, current platform/plan, event schema, identity/consent boundary, fallback, baseline, and value-test constraints. Name the catalog validator and technical owner. These inputs make it possible to separate a data repair, integration gap, and genuinely new model requirement.
You may share this article
Let professionals meet your challenge
Our certified specialists will find the most optimal solution for your business.